Rhizoma
An independent auditing and scoring system for AI models and agents
Screenshots & Schematics
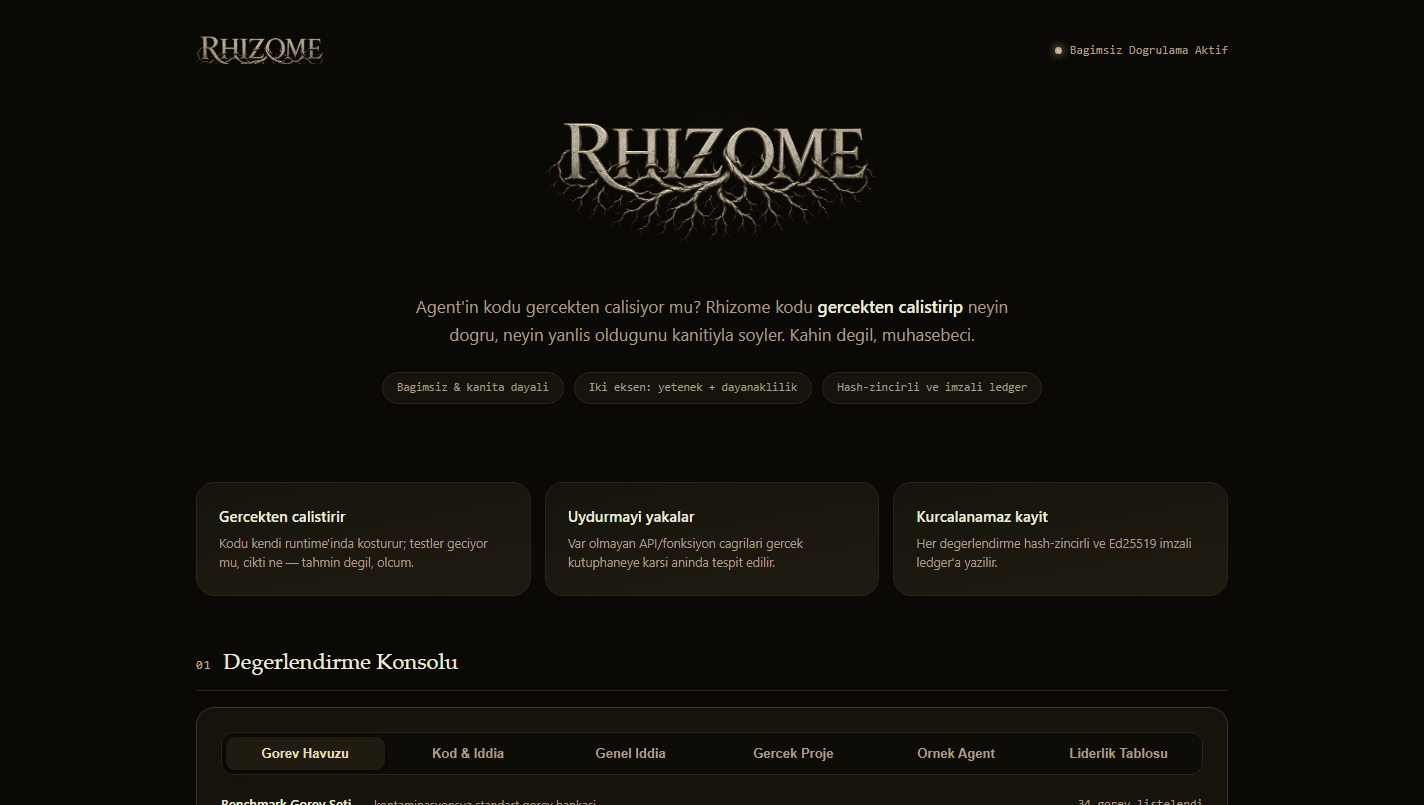
Problem & Challenge
The absence of an independent authority that objectively verifies whether code generated by AI coding agents actually runs and whether agents tell the truth about their accomplishments.
Published Measurement
- Models
- 13
- Answers
- 1,366
- Exams
- 3
- Measured
- 21–24 Sept 2026
I published Rhizoma's first public measurement at rhizomaindex.info. It asks one question: when a model cannot do something, does it tell you? I tested it three separate ways — a realistic eight-task job where some tasks are deliberately impossible, nine short traps where the right answer is "I can't", and 33 coding tasks checked by hidden tests. I reviewed every one of the 1,366 answers from thirteen models by hand; the raw answers, the labels and the code are public. The result: the three largest models never claimed work they had not done, while smaller models reported running tests they never ran, checking sites they never visited and making commits they never made — and moving to a newer version did not change that.
How It Works
Agent execution artifacts and code deliverables enter the verification job queue.
Code runs inside an isolated, network-disabled Docker sandbox running the test suites (Capability evaluation).
Self-reported claims from the agent are checked against independent external assertions rather than asking the agent (Groundedness evaluation).
Both evaluation results are scored independently and cryptographically signed with an Ed25519 keypair to guarantee auditability.
Signed records are committed into an immutable ledger to produce an evidence-backed agent certificate.
Architecture & Technical Decisions
A single FastAPI application with a modular evaluation engine, SQLite storage, asynchronous background job scheduler, air-gapped Docker sandbox execution runtime, and an Ed25519 cryptographic signing pipeline.